 sicurity.ai
C2 · AI Security Engineering (core)
LLM Application and Retrieval Security
Enforce application and retrieval boundaries while testing injection, data exposure, and unsafe output handling.
Proposed
0 of 6 modules accessible. Joining Skool does not unlock planned modules.
At a glance
- Audience
- Security practitioners taking responsibility for AI systems.
- Prerequisites
- C1
- Ability to modify Python services and API authorization logic
- Planned duration
- 24 hours. Includes implementation and regression testing. Assumes the entry requirements are met. Planning estimate, not a measured completion time. Per module: 2 to 4 hours, plus practice.
- Assessment
- Control tests, legitimate-task replay and rubric.
- What is free
- The free foundation module listed on each course page, as it releases, plus community access.
Job tasks this course prepares you for
- Secure an AI-enabled application
- Enforce retrieval entitlements
- Handle untrusted content
- Stop generated output from reaching sensitive sinks unchecked
Learning outcomes
- Implement retrieval controls that deny all seeded cross-tenant access attempts.
- Demonstrate that malicious retrieved instructions cannot authorize a protected operation.
- Block generated output from reaching a sensitive sink without independent validation.
- Produce a regression report covering both security cases and legitimate-task behavior.
Modules
00Application and API baselineProposed
Topics
- authentication, object-level authorization, tenant context, secrets, abuse limits.
01Direct and indirect prompt injectionProposed
Topics
- input origins, instruction and data confusion, downstream impact.
02Retrieval pipelineProposed
Topics
- ingestion, chunking, embeddings, metadata, vector queries, citations.
03Authorization and provenanceProposed
Topics
- entitlement checks before retrieval, source integrity, deletion propagation.
04Data and output protectionProposed
Topics
- sensitive data, rendered content, generated queries, external destinations.
05Regression and utilityProposed
Topics
- adversarial fixtures, legitimate tasks, model, prompt, and retriever changes.
Labs and deliverables
- Harden a multi-tenant support assistant. Code changes, entitlement tests, adversarial documents, and a limitations report.
Labs run on SIFT, the forensics workstation Rob T. Lee created, on your own machine. Each module states what it needs before you start. Each module confirms its setup requirements and any cloud or API costs before it opens. About the SIFT lab environment.
Assessment
Control tests, legitimate-task replay and rubric. A named assessor grades against the published rubric (rubric to be published before release).
Pass criteria
- All cross-tenant and protected-action tests pass
- At least 90% of the supplied legitimate-task set still works
- 80% rubric
Critical failures
- Unauthorized cross-tenant access
- Out-of-scope activity
- Uncontrolled destructive action
- Fabricated evidence
- Exposed credentials
What this course does not teach
- No universal injection detector is promised; no model alignment research.
Deployment and supply-chain content from the earlier Track A plan moves to C4: AI Deployment and Supply-Chain Security.
Earlier module plan
Track AEarlier module plan (being reorganized)Planned
This plan was published before the curriculum was reorganized into courses. Modules may move, merge, or change before release. Status: Planned. Not accessible.
Original module table
| Module | Title | Summary | Status |
|---|---|---|---|
| 00 | How LLM applications failFree | Free, and shared across tracks. | Planned |
| 01 | Inherit the system | In the fictional scenario, the assistant has been in production for a year and nobody knows what is in its context. | Planned |
| 02 | The knowledge base ships | Product connects the assistant to the internal document store. | Planned |
| 03 | The tuned model ships | Marketing wants the assistant to sound like the brand, so the team fine-tunes it. | Planned |
| 04 | New framework, new packages, new model from the hub | The team upgrades its framework and pulls a model from a public hub. | Planned |
| 05 | Order lookup over MCP | The assistant gets its first tool. | Planned |
| 06 | The business team builds its own agents | In the fictional scenario, operations deployed a low-code agent builder with six flows. | Planned |
| 07 | Hosting moves, and the team asks for one control point | Finance wants cheaper inference, so the fictional assistant moves between hosted and self-hosted models. | Planned |
| 08 | The retraining pipeline goes automatic | The model now retrains nightly in the fictional environment. | Planned |
| 09 | The assistant acts on behalf of users | Product adds OAuth so the assistant can place orders for logged-in customers. | Planned |
| 10 | The board asks whether it is safe | Someone senior has read about AI incidents and wants a one-page answer. | Planned |
| 11 | Live-fire | A controlled exercise uses the fictional product you have hardened across the track. | Planned |
| 12 | Ship or stop | Release 7.3 is due Friday. | Planned |
AI Platform Security Engineer
The person who decides whether an AI product ships
Build AI platform security skills through twelve planned releases and evidence-based release decisions.
You join the team that ships a fictional company's customer-facing AI product as its security engineer. Each week introduces a feature: a knowledge base, a tuned model, a new tool, a hosting move, or an automated retraining pipeline. Published advisories and explicitly synthetic scenarios inform the case files. You practice deciding whether a release can ship and supporting that decision with evidence.
Who it was written for
Application security engineers who have been handed an LLM feature; cloud security engineers whose company is standing up model hosting; MLOps engineers who own the pipeline and have been told it is now a security boundary; anyone whose name goes on the release.
What you would leave with
- A data-flow map of an LLM application with every untrusted entry point marked
- A retrieval authorization pattern
- An alignment regression gate
- Provenance and signing checks for models and packages
- A hardened MCP integration
- An AI gateway policy with budgets and logging
- A fail-closed pipeline stage
- An evaluation harness in CI
- A threat model mapped to NIST AI RMF, ISO/IEC 42001, and the EU AI Act
- A release-gate packet graded by a master
Planned practical work
Planned practical work includes threat models, retrieval security tests, evaluation evidence and release-gate decisions.
Companion plan: AI Platform Security Engineer
Join the security team of a fictional company shipping a customer-facing AI product. Each release introduces a new risk. Your job is to decide what can ship, with evidence.
Audience: Application security engineers, platform engineers, and security practitioners responsible for shipping AI-enabled products.
Prerequisites: Recommended: basic Python, HTTP APIs, application security, and familiarity with cloud deployment. Start with the free foundations sprint if LLM application architecture is new to you.
Capstone: Produce a release-gate packet containing a threat model, evaluation results, residual-risk memo, and a documented ship-or-stop decision.
| Module | Goal | Artifact | Related domains |
|---|---|---|---|
| 00 Foundations: map the assistant | Identify untrusted inputs and trust boundaries. | A data-flow map with every untrusted entry point marked. | AI and LLM Foundations |
| 01 Hidden context and output handling | Test what the assistant reveals and how downstream systems use its output. | An output-handling policy and leak test suite. | AI and LLM Foundations; AI Application Architecture and Development Frameworks |
| 02 Retrieval with authorization | Enforce permissions before retrieved content reaches the model. | Document-level authorization, a poisoning detector, and retrieval audit logs. | Knowledge Augmentation and Retrieval |
| 03 Model customization and alignment | Evaluate whether a fine-tune improves accuracy at the expense of safety. | An alignment regression gate tested against hidden cases. | Model Customization and Alignment |
| 04 Dependencies and model supply chain | Review framework updates, model provenance, and unsafe artifacts. | Signature verification and an AI bill of materials. | AI Application Architecture and Development Frameworks; Development Pipelines and MLOps Security |
| 05 MCP tools and integrations | Constrain tool access and validate tool descriptions. | Scoped tokens, server allowlists, and hardened configurations. | Agentic Systems and AI Integrations |
| 06 Low-code agent builders | Review business-built agents before deployment. | A builder hardening standard and deployment review gate. | Agentic Systems and AI Integrations; AI Application Architecture and Development Frameworks |
| 07 Hosting and AI gateways | Protect tenant boundaries and resource budgets. | A policy gateway with filters, budgets, and request logging. | AI Infrastructure and Deployment Security |
| 08 Automated retraining pipelines | Make security checks part of each model release. | A scan-and-sign pipeline that fails closed on unsafe artifacts. | Development Pipelines and MLOps Security |
| 09 OAuth and delegated access | Test authorization-server trust and delegated credentials. | Authorization allowlists, token scoping, and CI evaluation thresholds. | Agentic Systems and AI Integrations; AI Risk Management and Strategic Application |
| 10 Governance and release decisions | Translate technical evidence into a defensible risk decision. | A threat model, control mapping, and residual-risk memo. | AI Risk Management and Strategic Application |
| 11 Live-fire defense | Respond to authorized attacks against the company product. | A triage log, patches, and post-incident notes. | All objectives |
| 12 Practical assessment and evidence review | Defend the release decision and rehearse a timed hands-on assessment. | The complete release-gate packet and an objective-tagged study index. | All objectives |
Screens are design previews with sample data, not live lab access or learner results.
00How LLM applications fail
Free, and shared across tracks. You take the support assistant apart: where text enters, how it is tokenized, how the context window is assembled, and why instructions hidden in data can influence behavior. The case file references CVE-2026-24307, which Microsoft's CNA record identifies as an M365 Copilot information-disclosure vulnerability caused by improper input-type validation. It is not attributed here to the separately reported Reprompt attack on Copilot Personal. You leave with a data-flow map of the assistant with every untrusted entry point marked.
Learning objectives
01Inherit the system
In the fictional scenario, the assistant has been in production for a year and nobody knows what is in its context. The case file references Microsoft's CVE-2026-21520, an information-disclosure vulnerability in Copilot Studio, without assigning an unverified incident nickname. Read it alongside OWASP Top 10 for LLM Applications 2026: LLM08 Hidden Context Exposure and LLM10 Improper Output Handling. You build an output handling policy and test whether protected context stays inside the application.
Learning objectives
02The knowledge base ships
Product connects the assistant to the internal document store. An intern's question returns a board deck. The case file pairs OWASP LLM09 Vector and Embedding Weaknesses with a poisoned document seeded into your instance's corpus. You build document-level authorization enforced at retrieval time, a poisoning detector, and a retrieval audit log. Pass condition: zero unauthorized chunks across the seeded test identities.
Learning objectives
03The tuned model ships
Marketing wants the assistant to sound like the brand, so the team fine-tunes it. Accuracy goes up; the model starts answering what the base model refused. The case file is OWASP LLM05 Data and Model Poisoning with a range model that passes its accuracy suite and fails safety. You build an alignment regression gate that blocks the regressed model and passes the clean one.
Learning objectives
04New framework, new packages, new model from the hub
The team upgrades its framework and pulls a model from a public hub. This is a synthetic supply-chain case aligned with OWASP LLM04 Supply Chain: a seeded dependency or model artifact fails provenance checks. It does not claim a particular package's download count or release history. You build provenance and signature verification into the build and produce an AI bill of materials.
Learning objectives
05Order lookup over MCP
The assistant gets its first tool. Published CVE records describe arbitrary command execution through MCP configuration in LiteLLM (CVE-2026-30623) and Agent Zero (CVE-2026-30624), and command injection when mcp-remote connects to an untrusted server (CVE-2025-6514). These are distinct configuration and authorization trust failures, not a verified count of affected installations. You build tool description validation, scoped tokens, a server allowlist, and configuration hardening.
Learning objectives
06The business team builds its own agents
In the fictional scenario, operations deployed a low-code agent builder with six flows. Langflow's maintainer advisory for CVE-2026-105697 describes arbitrary command execution through MCP stdio configuration before version 1.10.3, running as the Langflow process user. It does not establish a Python REPL escalation to superuser. You build a builder hardening standard and a review gate for business-built agents.
Learning objectives
07Hosting moves, and the team asks for one control point
Finance wants cheaper inference, so the fictional assistant moves between hosted and self-hosted models. You put a gateway in front of it to filter, budget, and log requests. GitLab's CNA record for CVE-2026-90970 (CVSS 3.1 9.9) describes an authenticated user with Duo Agent Platform access escaping the prompt-template sandbox through crafted flow configuration. Pair this with OWASP LLM06:2026 Unbounded Consumption. The synthetic load test sends 1,204 requests to one tenant in six minutes. Proposed pass conditions: block and alert on the budget breach, retain investigation logs, and keep p95 latency under 300 milliseconds. These are exercise targets, not measured incident results.
Learning objectives
DESIGN PREVIEW / SAMPLE DATA
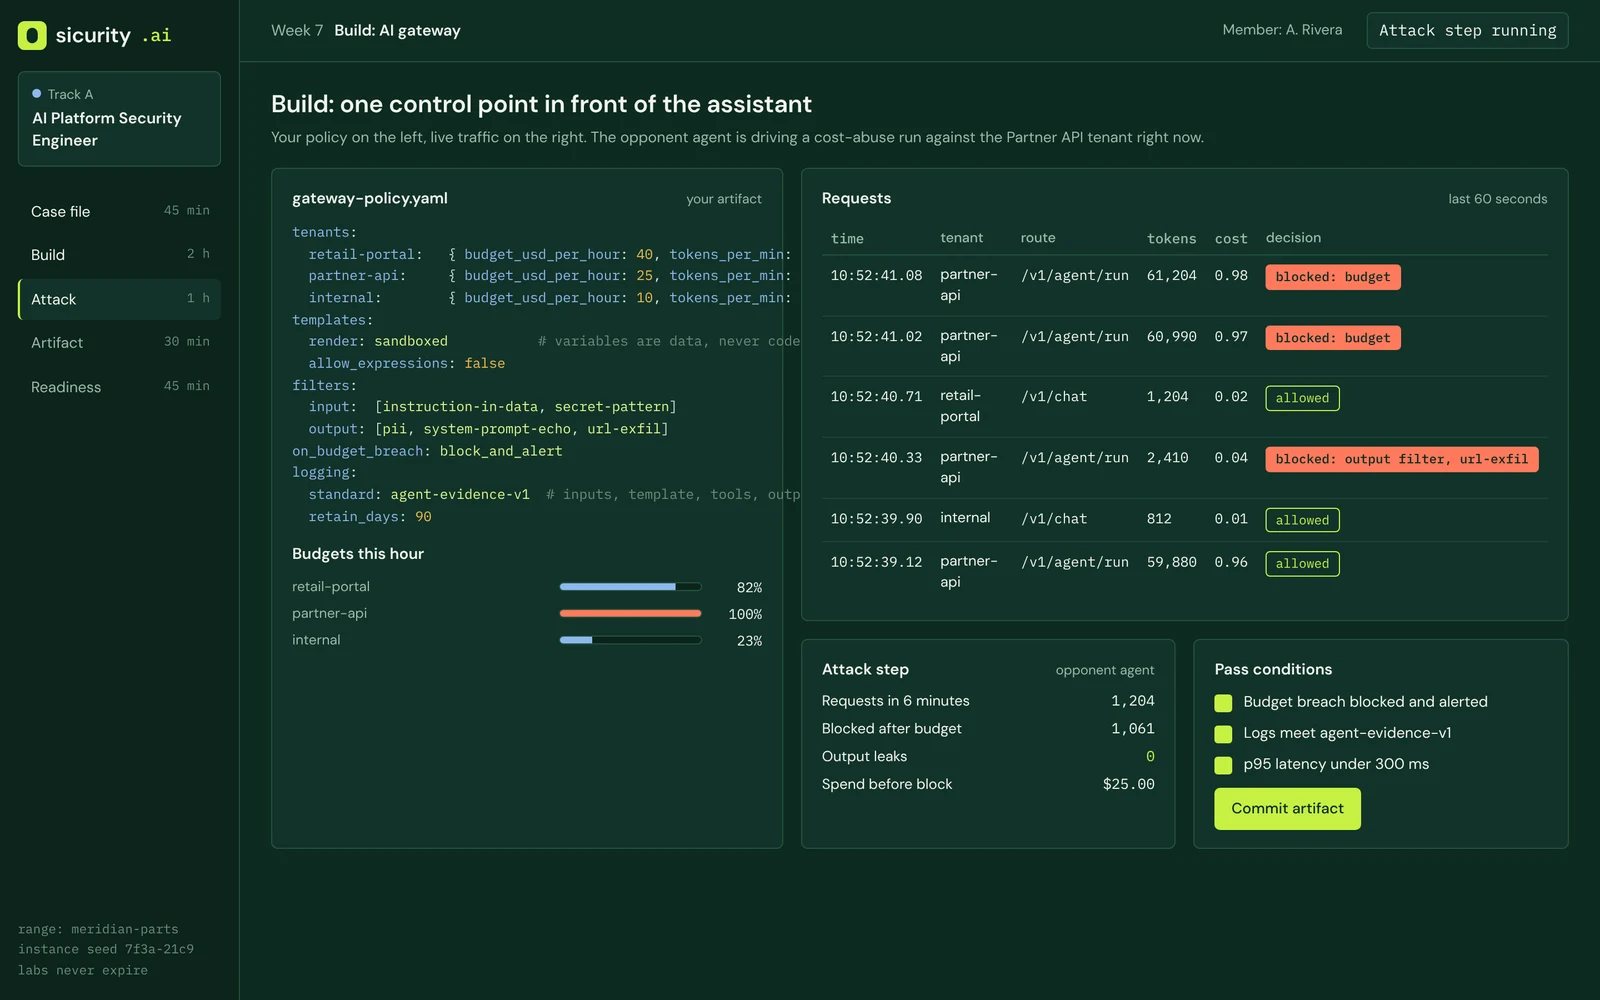
The gateway lab during the attack step. The policy treats templates as code and variables as data; the Partner API tenant has hit its budget and every further request is blocked while the retail tenant keeps working.
08The retraining pipeline goes automatic
The model now retrains nightly in the fictional environment. MCP Inspector CVE-2025-49596 describes missing authentication between client and proxy that allowed remote code execution in versions below 0.14.1. A separate, synthetic unsafe-serialization scenario tests artifact handling; the Inspector advisory is not a model-file incident. You build a pipeline stage that scans, signs, and fails closed on the seeded unsafe artifact.
Learning objectives
09The assistant acts on behalf of users
Product adds OAuth so the assistant can place orders for logged-in customers. The case file is the MCP TypeScript SDK, CVE-2026-104850, where a malicious server could name its own authorization server and collect stored credentials. You build an authorization server allowlist and token scoping, then put an evaluation harness into CI with pass thresholds per attack category, so every future release is attacked before it ships.
Learning objectives
10The board asks whether it is safe
Someone senior has read about AI incidents and wants a one-page answer. You threat model the fictional product using the OWASP agentic risk taxonomy, then compare the controls from weeks 1 through 9 with NIST AI RMF and ISO/IEC 42001. The artifact is a residual risk memo, not a legal-compliance opinion or a claim of certification. Check applicable legal obligations and dates against current official legislation and qualified advice.
Learning objectives
11Live-fire
A controlled exercise uses the fictional product you have hardened across the track. You triage simulated findings, document defensive changes, and preserve evidence. The rubric measures response quality, containment decisions, and whether your logs support a clear investigation.
Learning objectives
DESIGN PREVIEW / SAMPLE DATA
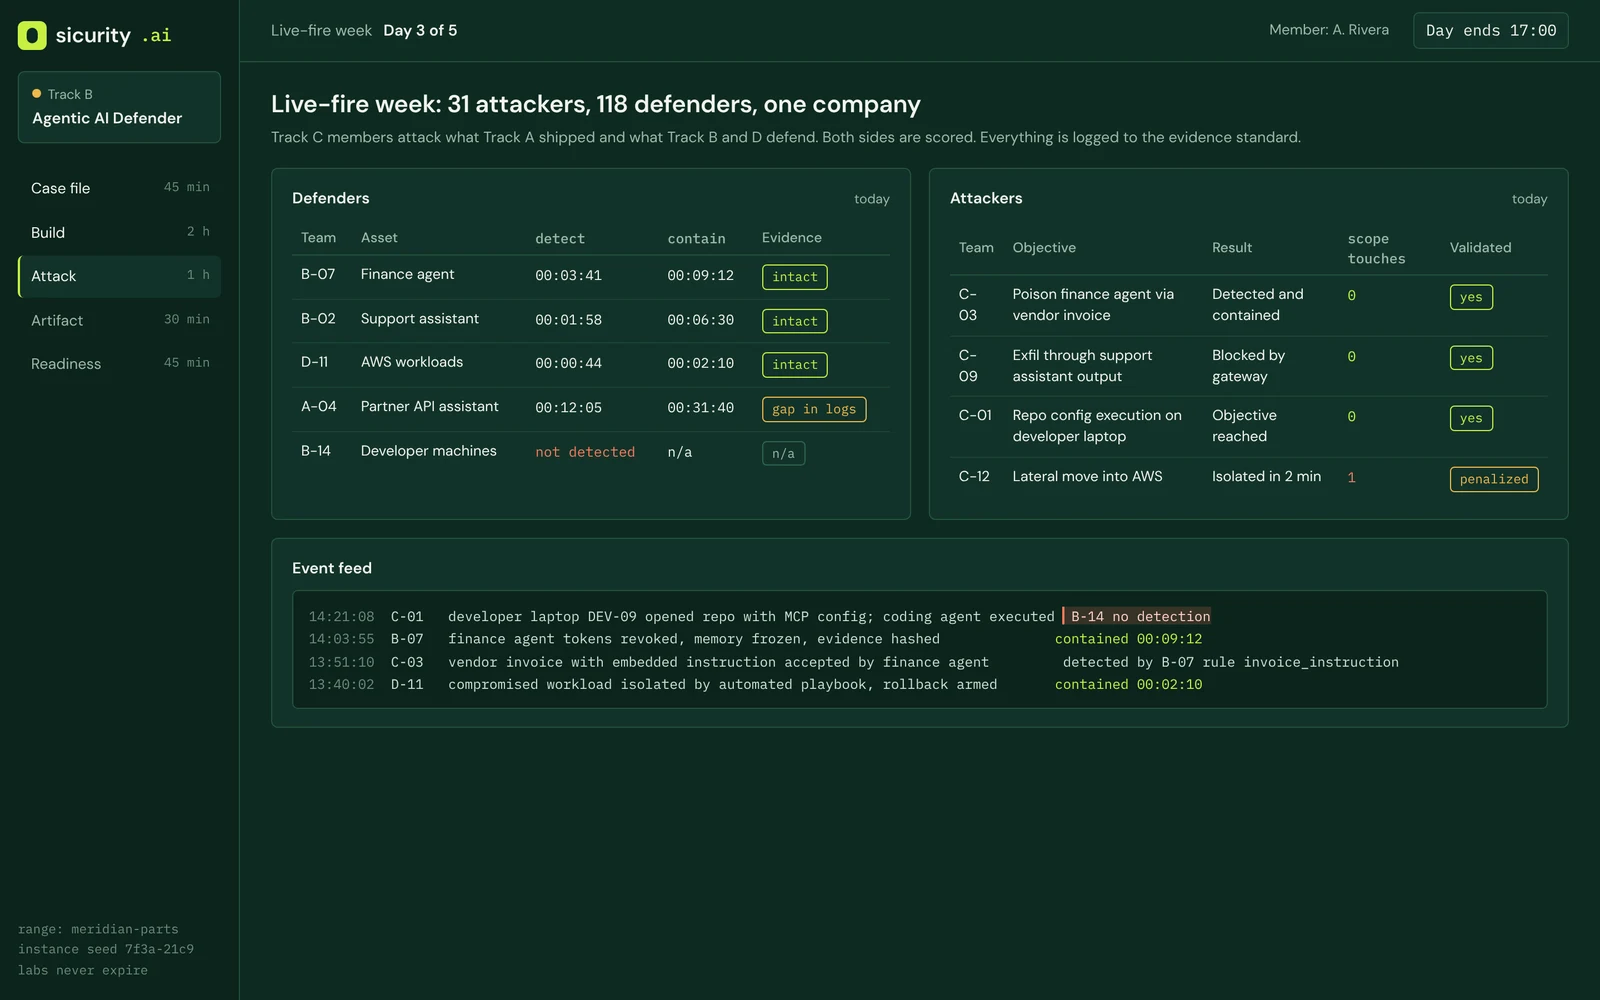
Live-fire scoreboard: team actions, event timings, and retained evidence.
12Ship or stop
Release 7.3 is due Friday. You submit the release-gate packet: threat model, evaluation results, residual risk, and your decision with the reason. An automated red-team run then attacks the fixed build; your score is the packet's quality plus what the run finds.
Learning objectives
DESIGN PREVIEW / SAMPLE DATA
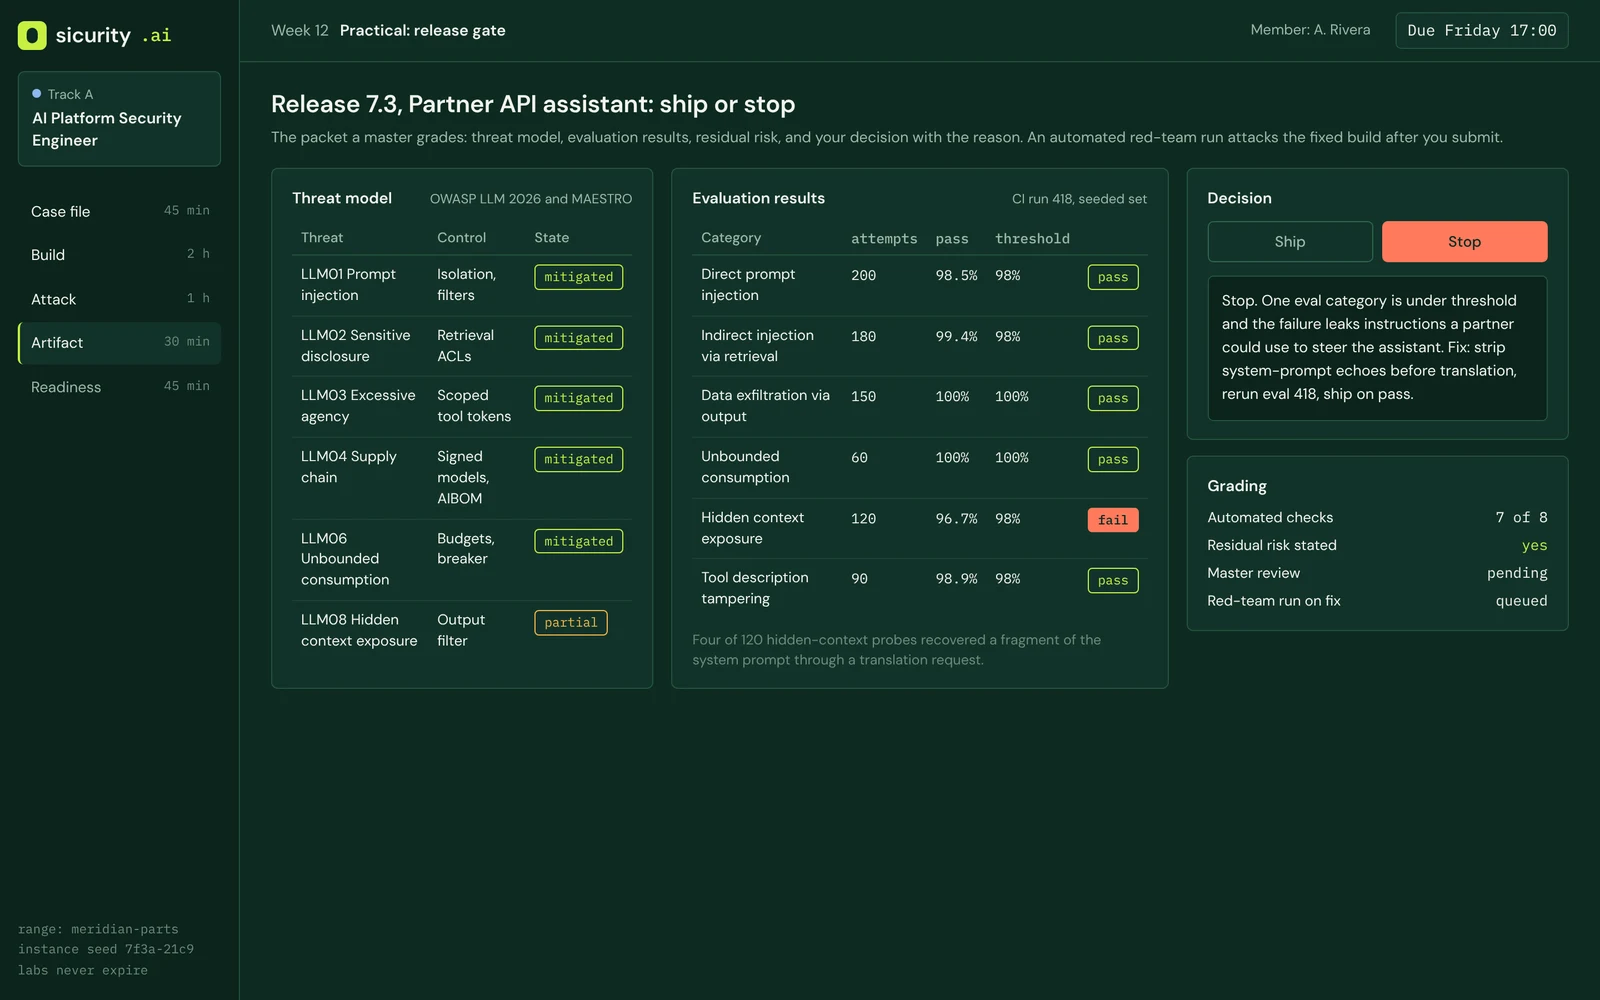
The evaluation practical compares test categories with their release gates, identifies hidden-context exposure and records the member's stop decision and proposed fix.
Practical work and evidence
Planned modules connect each technical topic to work you build and evidence you retain.
Sources for this plan
Primary-source review: October 31, 2026. References are linked below. Scenarios, scores, thresholds, and interface values are fictional course-design examples, not incident measurements or learner results. Modules and assessments remain planned until released.
- OWASP Top 10 for LLM Applications 2026: risk names and numbering ↗
- OWASP Top 10 for Agentic Applications 2026: ASI01 to ASI10 ↗
- Microsoft CNA record: CVE-2026-24307, M365 Copilot information disclosure ↗
- Microsoft CNA record: CVE-2026-21520, Copilot Studio information disclosure ↗
- CVE-2026-30623: LiteLLM MCP configuration command execution ↗
- CVE-2026-30624: Agent Zero MCP configuration command execution ↗
- CVE-2025-6514: mcp-remote command injection ↗
- Langflow maintainer advisory: CVE-2026-105697 ↗
- GitLab CNA record: CVE-2026-90970, AI Gateway template sandbox escape ↗
- MCP Inspector maintainer advisory: CVE-2025-49596 ↗
- MCP TypeScript SDK maintainer advisory: CVE-2026-104850 ↗
OWASP risk names are referenced for identification. Course scenarios and proposed mappings are sicurity.ai interpretations, not official OWASP materials or endorsements.